How AI Transforms Expense Management: From Policy Compliance to Real-Time Automation

The Business Impact: Why Expense Management Matters More Than Ever

Travel and expense management sits at the intersection of employee satisfaction, financial control, and operational compliance. Organizations today face a fundamental challenge: employees expect frictionless reimbursement experiences while finance teams must enforce policy, prevent fraud, ensure regulatory compliance, and maintain accurate tax and accounting records. The expense lifecycle—from travel request through final reconciliation—involves dozens of decision points, manual handoffs, and systems integrations. Traditional approaches rely on spreadsheets, email approval chains, and batch processing, leaving organizations vulnerable to policy violations, delayed reimbursements, and compliance gaps. The business imperative is clear: compress cycle time, eliminate exceptions, and reduce overhead without sacrificing control or visibility.

A woman reviews receipts and calculates expenses at a desk with a pink calculator. (Photo by https://kaboompics.com/ on Pexels)

Artificial intelligence addresses this imperative directly. By mapping across the entire expense operating model—from initial travel requests through final accounting entries—AI-driven solutions automate decision-making, flag exceptions in real time, and provide continuous visibility into spending patterns and compliance posture. The result is measurable: reduced processing costs, faster reimbursements, improved policy adherence, and better data for strategic spend analysis.

The Expense Operating Model: Where AI Creates Value

Effective expense management integrates five critical domains: employee initiation, corporate policy enforcement, payment processing, accounting and tax, and compliance monitoring. Each domain involves distinct processes, systems, and human decision points. An employee initiates travel by submitting a request with estimated costs and business justification. A manager or policy engine approves or denies the request based on budget, policy rules, and prior spending patterns. The trip occurs, receipts accumulate, and the employee submits an expense report. Finance teams validate receipts, match them to policies, reconcile charges, and route reimbursements. Finally, accounting systems classify expenses, apply tax treatment, and feed data to regulatory and audit systems.

This operating model is inherently complex because each stage connects to others: a denied travel request cascades to a revised plan; a missing receipt triggers an exception that blocks reimbursement; a misclassified expense creates downstream tax or audit issues. Traditional systems handle this complexity through manual intervention—exception queues, approval workflows, email escalations. AI reimagines this model by embedding intelligent decision-making at every stage, connecting the fragments into a unified, end-to-end process that operates with minimal human intervention yet maintains full visibility and control.

Agentic Workflows: Automating the Decision Cascade

Agentic AI systems—software agents that perceive context, reason through policies, and make autonomous decisions—are ideally suited to expense management. Unlike rule-based systems that apply static logic, agents learn from historical data, adapt to policy changes, and handle exceptions gracefully. A travel request agent, for example, evaluates a flight booking request by checking budget remaining for the business unit, comparing the proposed fare to historical spend, confirming compliance with preferred vendor rules, and assessing whether the travel purpose aligns with corporate strategy. If the request meets all criteria, the agent auto-approves and books the flight. If risks emerge—an unusually expensive hotel, a missing business justification—the agent routes the request to a human with context-specific recommendations.

Similarly, an expense report agent ingests receipt images, uses optical character recognition to extract line items and amounts, matches expenses to pre-approved categories, flags potential policy violations, and routes compliant reports directly to reimbursement without human review. The agent monitors for patterns: repeated charges from non-preferred vendors, meals in restricted categories, late submissions that suggest poor planning. Over time, it learns which exceptions are genuine (valid business reasons) versus concerning (policy drift or fraud signals).

The power of agentic workflows lies in their ability to operate at scale without proportional increases in headcount. A finance team of five can process thousands of expense reports monthly when agents handle 80-90% of cases autonomously, reserving human judgment for genuinely ambiguous situations.

Real-World Use Cases Across the Lifecycle

Travel request optimization illustrates AI’s value in the earliest stage. Before an employee books travel, an intelligent system provides cost guidance: comparing flights across preferred vendors, suggesting cheaper alternatives that meet schedule requirements, and highlighting policy restrictions before the traveler commits. This front-end intervention is more effective than post-trip denials because it prevents rejected requests, reduces employee frustration, and eliminates wasted booking fees.

Receipt validation and categorization represents another high-impact use case. Employees submit receipts in multiple formats—photographs, PDFs, email confirmations—often with unclear vendor names and line items. AI agents extract structured data, recognize merchant categories, and automatically classify expenses. A blurry receipt from a café is recognized as a meal expense; an auto rental confirmation is categorized as transportation; an app store receipt is flagged as potentially personal. Human reviewers see only exceptions, reducing review time by 70-80%.

Duplicate detection and fraud prevention add another layer. Agents identify duplicate submissions, unusual patterns (a single employee with 10x normal meal expenses), or high-risk vendors. They cross-reference corporate credit card data against submitted reports, surfacing discrepancies. They apply machine learning models trained on historical fraud cases to score each submission for risk.

Policy compliance monitoring operates continuously. Agents track which departments consistently exceed meal budgets, which employees book non-preferred vendors most often, and whether policy violations correlate with business unit or geography. This visibility allows finance teams to intervene proactively—retraining high-risk departments, renegotiating vendor terms, or adjusting policies where they conflict with actual business needs.

Governance, Control, and Human Oversight

Automation at scale requires robust governance. Organizations cannot simply delegate expense decisions to software and assume compliance. Governance frameworks must define when agents decide autonomously, when they escalate to humans, and how decisions are audited and adjusted. A well-designed governance model establishes decision thresholds (e.g., agents approve requests under $5,000; humans approve larger requests), policy rules (e.g., agents enforce meal limits but flag first-time policy deviations for context), and escalation protocols (e.g., if an agent’s decision confidence is below 70%, escalate to human review).

Critical to governance is auditability. Every agent decision must be logged with supporting context: what data inputs informed the decision, which policy rules applied, whether the decision was overridden by a human, and whether subsequent events (e.g., the expense was approved on appeal) suggest the agent’s decision was questionable. These audit trails enable continuous improvement: if human reviewers consistently override agent decisions in a particular category, the underlying model or policy rule likely needs adjustment. They also satisfy compliance requirements, providing clear evidence of internal controls for auditors and regulators.

Organizations must also establish feedback mechanisms. When humans approve expenses that agents would have denied, that data trains future models. When expense reports are later disputed or audited, those signals refine fraud detection models. This closed-loop learning means governance frameworks must be reviewed quarterly to reflect emerging patterns, new policy rules, or changes in risk tolerance.

Implementation: From Pilot to Enterprise Scale

Deploying AI-driven expense management requires careful sequencing. Organizations typically begin with a pilot focused on a single use case—receipt categorization, for example—involving a subset of employees. This pilot establishes baseline metrics (current processing time, accuracy, cost), trains initial models on historical data, and identifies integration points with existing systems.

Success in the pilot requires attention to data quality and human change management. Many organizations discover that their historical expense data is inconsistent (inconsistent categorization, incomplete merchant information, missing receipts). This data must be cleaned before training models. Simultaneously, employees and managers must understand how the new system works and why automation exists. Finance teams need training on governance frameworks, escalation protocols, and how to interpret agent recommendations.

Once pilots succeed, organizations expand to additional use cases and larger user populations. A mature deployment automates the entire lifecycle: travel requests are evaluated and approved by agents, expenses are categorized and validated automatically, duplicate and fraud detection runs continuously, and compliance reports are generated without human intervention. Finance teams shift from transaction processing to strategic analysis, using AI-generated insights to optimize vendor contracts, refine travel policies, and understand spending patterns by cost center and business objective.

The Path Forward: Integrating AI Into Expense Operations

Organizations that integrate AI comprehensively into expense management gain competitive advantages that extend beyond finance. Faster reimbursements improve employee satisfaction and retention. Automated compliance reduces audit risk and accelerates year-end close. Better spending visibility enables more strategic procurement and cost management. Importantly, these benefits scale: a process that is 80% automated for 100 employees can scale to 10,000 employees without proportional increases in overhead.

The transformation from manual, siloed expense management to AI-driven, integrated operations is neither instantaneous nor trivial. It requires investment in technology, governance discipline, and change management. But the business case is compelling: lower costs, faster cycles, better compliance, and the ability for finance teams to focus on strategic priorities rather than exception handling. Organizations that make this transition today establish a foundation for continuous improvement and competitive advantage in an increasingly regulated, data-driven business environment.

Read more

Eliminating Sales Closure Delays: How AI Transforms Order Entry and Deal Processing

The Hidden Cost of Manual Sales Workflows

Sales organizations operate under constant pressure to accelerate revenue cycles while maintaining accuracy. Yet many still rely on manual processes for deal closure and order entry—tasks that consume hours of administrative effort, introduce transcription errors, and create critical bottlenecks between signed agreements and fulfilled orders. Representatives spend valuable selling time chasing signatures, collecting paperwork, and inputting order details into multiple systems. When this burden multiplies across dozens of sales staff, the cumulative effect is substantial: slower deal-to-cash timelines, increased error rates that trigger corrections and delays, and lost productivity that directly impacts revenue outcomes.

Miniature shopping cart placed on a laptop keyboard, symbolizing online shopping. (Photo by Atlantic Ambience on Pexels)

The operational friction extends beyond individual deal losses. Manual order entry creates downstream chaos—finance teams must validate data quality, customer success struggles with incomplete or misformatted information at handoff, and fulfillment operations face preventable delays. Contracts languish in inboxes awaiting key signature sections; orders contain transcription errors that require rework. For enterprises selling complex products or managing high transaction volumes, this manual machinery becomes unsustainable. The organization is essentially choosing to operate at a pace constrained by human data-handling capacity rather than market demand.

Intelligent Automation: Redefining the Closure Process

Artificial intelligence addresses this structural problem by automating the mechanical and repetitive components of sales closure while maintaining human judgment where it matters most. Rather than replacing salespeople, AI becomes their force multiplier—handling signature collection workflows, extracting key terms from executed agreements, and populating order systems with accuracy that exceeds manual entry. The technology ingests documents, identifies required fields and contractual obligations, validates completeness, and flags exceptions for human review. This hybrid model preserves the relationship and negotiation aspects that define professional sales while eliminating the administrative drudgery.

The acceleration is immediate and quantifiable. Deal closure cycles compress from days to hours because approvals, document assembly, and order creation happen in parallel rather than sequentially. Salespeople receive automated alerts when documents are ready for signature, ensuring no deal stalls in limbo. Once executed, contracts move directly into processing workflows without waiting for manual rekeying. Error rates plummet because structured extraction replaces error-prone manual transcription, and validation rules catch inconsistencies before they propagate downstream. The result is a sales operation that moves at machine speed on routine tasks while concentrating human expertise on closing strategy and customer relationships.

Automating Order Entry Without Sacrificing Accuracy

Traditional order entry represents one of the highest-friction points in the sales-to-fulfillment chain. Representatives manually transcribe deal terms into order management systems, often working from multiple document sources—contracts, email threads, specification sheets, and pricing agreements. Keyboard entry introduces typos; misread quantities lead to oversized orders; incomplete information cascades into customer success workflows that lack critical context. For high-volume operations, the administrative cost rivals the value generated by each transaction. AI-driven order entry eliminates this intermediary step by extracting structured data directly from source documents and feeding it into downstream systems with verified accuracy.

Consider a sales organization closing 20 contracts daily with an average order value of $50,000 and 15 line items per order. Manual entry at 10 minutes per order consumes 200 staff-hours weekly—equivalent to five full-time employees doing nothing but data entry. Errors requiring correction consume additional hours. Automated extraction with human validation—confirming only flagged exceptions rather than every field—reduces that burden to 5-10% of original effort while improving accuracy from 95% to 99%+. The savings accumulate rapidly: faster cash conversion, fewer fulfillment exceptions, improved customer onboarding, and freed sales capacity to pursue additional pipeline.

Connecting the Chain: From Signature to Fulfillment

The most sophisticated implementations view closure and order entry not as isolated tasks but as integrated stages in a continuous handoff process. When a contract executes, AI automatically triggers a sequence: document validation, obligation extraction, system population, and downstream notification to finance, customer success, and operations teams. Each function receives pre-populated, verified information rather than hunting for attachments or reconstructing deal scope from email chains. This integration eliminates the friction points where information gets lost or distorted in handoff.

Real-world scenarios illustrate the impact. A technology company executing a $2 million enterprise contract with complex implementation schedules and custom pricing tiers can now move from signature to onboarding kickoff in 2 hours rather than 3-5 business days. Finance receives verified revenue recognition data automatically. Customer success teams access complete contract terms, deployment timelines, and support tier assignments without requesting clarification. Operations begin resource planning the day a deal closes rather than days later when someone finally files the signed contract. The organization captures value from its closed sales immediately rather than leaving money on the table during administrative delays.

Implementation Considerations and Organizational Readiness

Deploying intelligent automation in sales operations requires more than installing software—it demands thoughtful change management and process redesign. Organizations must first audit existing workflows to identify where AI creates the greatest leverage: high-volume transaction types, error-prone manual fields, or processes with expensive downstream corrections. Not every deal requires identical processing; a small contract following a standard template needs different automation than complex multi-party agreements with custom terms. Effective implementations establish different processing pathways for different deal types.

Data quality and system integration form the foundation for success. If customer information is fragmented across disconnected systems, if contract templates lack standardization, or if order management platforms resist integration, AI systems will struggle to perform reliably. Organizations should prepare by consolidating data sources, standardizing document templates where feasible, and ensuring that downstream systems can ingest programmatically-delivered information. Team training is equally critical—sales staff need to understand how the technology augments their workflow, compliance teams must verify that automation meets regulatory requirements, and operations personnel must learn how to intervene when exceptions are flagged.

Measuring Impact and Capturing Organizational Value

The business case for intelligent closure and order entry automation rests on concrete metrics: reduction in deal-to-cash cycle time, improved accuracy in order data, decreased administrative headcount requirements or redeployed effort, and acceleration in revenue recognition. A mid-market software company might measure success as closing 48-hour contract processing times (down from 5 days), reducing order entry errors to below 0.5%, and recapturing 500 hours of monthly administrative labor for higher-value sales and support work. These metrics cascade into financial impact: faster cash recognition, lower correction costs, and improved customer satisfaction from reduced onboarding delays.

Beyond immediate efficiency gains, automation creates organizational capabilities that compound over time. With fewer people consumed by administrative tasks, sales teams can handle larger territories and higher deal volumes without proportional headcount increases. Finance gains better visibility into contract terms and revenue obligations. Customer success begins projects better informed about scope and expectations. Operations can forecast resource requirements more accurately. The organization becomes faster and more predictable—qualities that matter increasingly in competitive markets where sales velocity determines market share and customer satisfaction depends on seamless handoff experiences.

The Future of Intelligent Sales Operations

Intelligent automation in sales closure and order entry represents more than incremental efficiency—it signals a fundamental shift in how enterprises operate their revenue functions. As the technology matures and integrates deeper with existing systems, organizations that adopt it gain compounding advantages: faster growth without proportional cost increases, improved customer experiences through reduced delays and errors, and employees focused on judgment and relationship-building rather than data transcription. For enterprises determined to compete on speed and reliability, this transformation has moved from innovation to operational necessity.

References:

  1. https://www.leewayhertz.com/ai-in-sales-closure-and-order-entry/

The Business Case for AI in Modern Order Management Systems

Organizations processing hundreds or thousands of orders daily face a fundamental challenge: how to maintain speed, accuracy, and profitability while scaling operations. Traditional order management relies on manual processes, spreadsheets, and rule-based systems that struggle under volume, introduce human error, and limit visibility across the supply chain. Forward-thinking enterprises are solving this problem through a transformative technology that directly impacts revenue, cost structure, and customer retention.

A cashier uses a touchscreen system for taking orders in a restaurant setting. (Photo by iMin Technology on Pexels)

AI in order management represents a fundamental shift in how organizations handle order processing, fulfillment, and customer interactions. Rather than treating orders as isolated transactions to process sequentially, AI enables enterprises to view order management as an intelligent, interconnected system where each decision—from routing to pricing to inventory allocation—is informed by predictive insights and real-time data. This shift delivers measurable business outcomes: orders process faster, errors drop dramatically, and resources focus on high-value decision-making rather than routine tasks.

The Measurable Business Outcomes

When AI systems assume routine order management tasks, the operational improvements cascade through the entire organization. Order processing time typically compresses by 40-60%, reducing fulfillment timelines and improving customer satisfaction scores. Accuracy rates climb to 99%+ as AI eliminates data entry errors, transposition mistakes, and missed edge cases that plague manual workflows. Processing costs per order decline significantly since intelligent automation handles routine decisions at machine speed, freeing expensive human staff for complex exception handling and relationship management.

Beyond efficiency metrics, AI delivers strategic advantages in revenue capture and customer experience. Intelligent order routing maximizes profitability by considering real-time inventory levels, shipping costs, margin contribution, and delivery commitments simultaneously—optimizations that manual systems cannot perform at scale. Demand forecasting becomes accurate enough to inform production planning and inventory positioning, reducing both stockouts and carrying costs. Customer lifetime value increases as faster fulfillment, accurate shipments, and proactive communications build loyalty and repeat purchases.

How AI Powers Intelligent Order Processing

AI for order management operates through several interconnected mechanisms that work together to transform order handling. Natural language processing (NLP) automatically parses incoming orders from email, web forms, EDI feeds, and messaging platforms, extracting order details and flagging unusual requests for human review. Machine learning models classify orders by complexity, channel, customer profile, and fulfillment requirements, routing each order through the optimal processing path. Predictive algorithms estimate demand, identify cross-sell opportunities, and recommend dynamic pricing strategies that maximize revenue while honoring competitive positioning.

The system continuously learns from historical data and real-time outcomes, improving accuracy and efficiency incrementally. When humans resolve exceptions—unusual order patterns, inventory conflicts, or customer requests—the AI system captures these decisions and adjusts its models accordingly. This creates a virtuous cycle where the more orders the system processes, the more intelligent it becomes. Over time, the human involvement shifts from routine task execution to strategic exception handling and system refinement.

Critical Use Cases Transforming Order Management

Demand forecasting powered by AI reduces inventory costs while preventing stockouts. By analyzing historical patterns, seasonal trends, promotional calendars, and external factors like market conditions or competitor activity, AI models predict customer demand with surprising precision. Inventory planners receive probabilistic forecasts—not just point estimates—that account for uncertainty and allow them to set appropriate safety stock levels. Small and medium businesses particularly benefit, as AI-driven forecasting gives them analytical capabilities formerly available only to large enterprises with dedicated teams.

Intelligent order routing determines the optimal fulfillment location for each order based on inventory availability, delivery speed requirements, shipping costs, and customer location. AI systems evaluate multiple fulfillment options simultaneously, selecting the path that maximizes profitability while meeting customer delivery expectations. When inventory is constrained, the system intelligently allocates stock to orders with highest margin or customer priority. For businesses operating multiple fulfillment centers or drop-shipping networks, this capability alone can reduce costs by 15-25% while improving delivery performance.

Automated exception detection and escalation ensures that unusual orders receive appropriate attention. AI systems identify orders that deviate from normal patterns—unusually large quantities, new customer profiles, geographic anomalies, or suspicious payment patterns—and route them to fraud teams or compliance reviewers. Conversely, straightforward orders process automatically without human review, dramatically reducing cycle time for the majority of transactions while maintaining necessary controls.

Implementation Realities and Considerations

Successful AI deployment requires both technical and organizational preparation. Organizations must first establish clean, consistent data—order history, customer records, inventory levels, and fulfillment performance across several years. Dirty data, incompatible systems, and inconsistent classification schemes undermine AI model accuracy. Many enterprises spend 30-40% of implementation effort on data cleanup and consolidation before model training begins. This is not wasted effort; it also improves operational visibility and reduces downstream errors in traditional systems.

Change management deserves equal emphasis as technology deployment. Order management teams understandably worry about job displacement when AI assumes routine tasks. Successful organizations frame AI implementation as task transformation rather than elimination—automation handles routine decisions, freeing skilled staff to resolve complex issues, manage customer relationships, and optimize supply chain strategy. Training programs should prepare teams to work alongside AI systems, interpret their recommendations, and override decisions when business context requires human judgment. The most mature implementations treat AI as a decision support system that amplifies human expertise rather than replacing it.

Building the Business Case for Investment

The financial justification for AI in order management typically emerges from labor savings, cost reduction, and revenue capture. Direct labor savings arise from automating data entry, order classification, and straightforward fulfillment decisions. Cost reductions appear through improved inventory positioning, optimized fulfillment routing, and reduced error correction expenses. Revenue improvements come from better demand forecasting that prevents stockouts, dynamic pricing that captures available margin, and customer experience improvements that drive repeat purchases. Most organizations see return on investment within 12-18 months, with ongoing improvements as model accuracy increases.

The business case should account for both direct and indirect benefits. Indirect benefits—faster time to market for new products, reduced cash conversion cycle through optimized inventory, improved customer retention through faster fulfillment—often exceed direct cost savings. Risk reduction also has value; reduced order errors mean fewer chargebacks, returns, and customer service incidents. As enterprises increasingly differentiate on fulfillment speed and accuracy, AI-powered order management becomes not just a cost reduction lever but a competitive necessity that enables new business models and market segments.

The Path Forward

AI in order management has transitioned from experimental technology to operational standard in sophisticated enterprises. The competitive advantage accrues to early adopters who capture efficiency gains while competitors continue with manual processes. Organizations beginning their journey should start with high-volume, lower-complexity order types to build expertise and confidence before expanding to edge cases and complex scenarios. Partnerships with technology providers who understand both AI capabilities and order management domain requirements accelerate implementation and reduce deployment risk.

The trajectory is clear: intelligent order management systems will become table stakes rather than differentiators as the technology matures and vendor solutions improve. Organizations that master AI-powered order management today build the operational foundation for tomorrow’s supply chain—one that responds to demand intelligently, fulfills customer commitments reliably, and competes on speed and accuracy rather than simply cost.

How AI Transforms Fashion Operations: From Design to Retail Floor

Fashion companies that have deployed artificial intelligence across their operating model report measurable gains in decision velocity, inventory accuracy, and revenue optimization. When implemented strategically, AI doesn’t merely automate tasks—it fundamentally reshapes how fashion businesses forecast demand, develop products, and serve customers. The difference between leading fashion enterprises and laggards increasingly comes down to how effectively they’ve embedded AI into core workflows. This transformation requires understanding where AI creates the highest value and how to deploy it across the entire value chain.

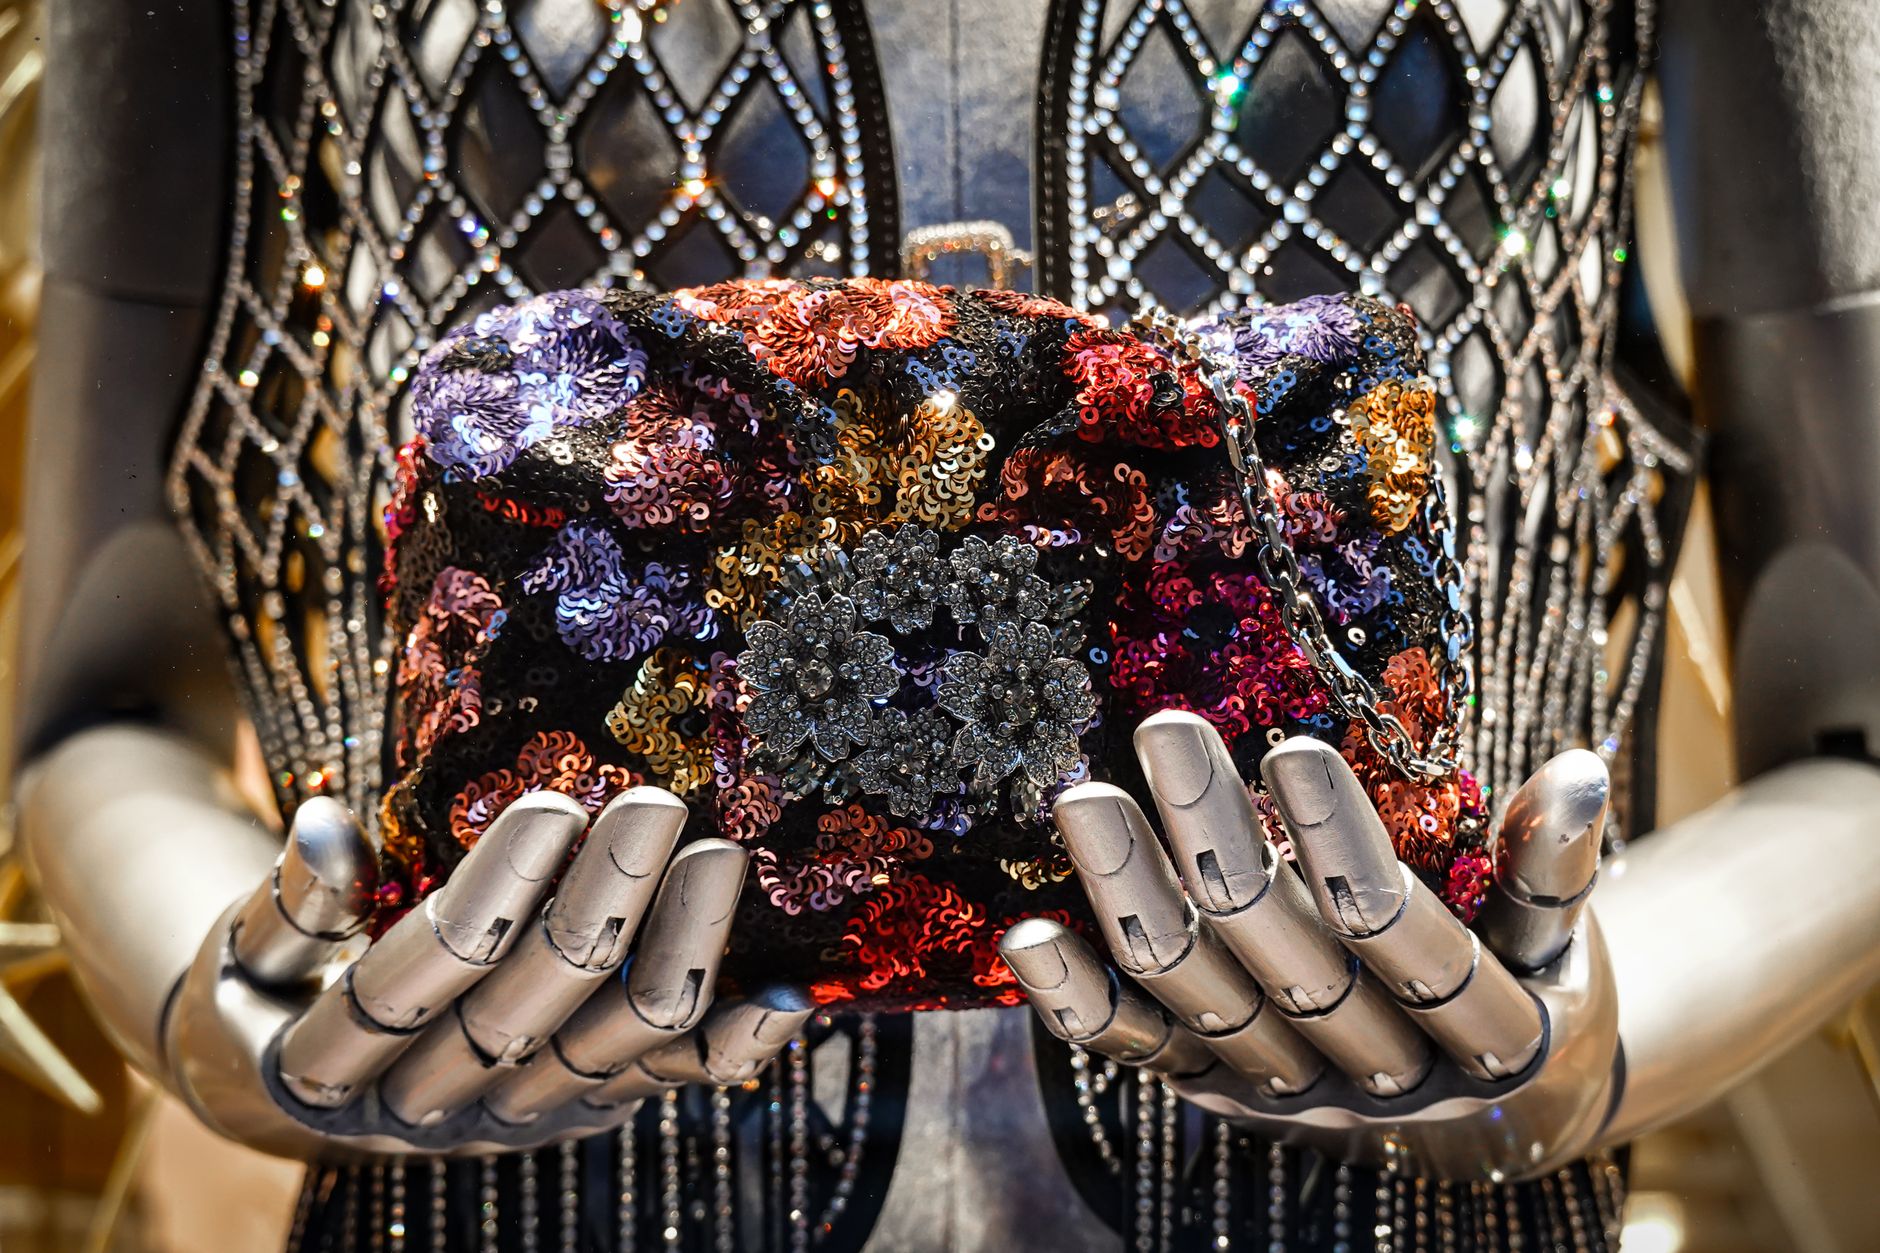
A fashion mannequin showcases a colorful sequin handbag held gracefully by robotic hands. (Photo by Magda Ehlers on Pexels)

The Business Case: Why Fashion Enterprises Are Turning to AI

The fashion industry operates under intense structural pressure. Product lifecycles compress by the quarter, consumer preferences shift rapidly, and inventory management carries enormous financial risk. A single misjudgment—overstock on the wrong color, understock on a viral trend—can erode margins significantly. Simultaneously, fashion organizations struggle with siloed data, manual processes that take weeks to complete, and decision-making based on intuition rather than evidence. These inefficiencies create a cost structure that competitors can undercut and leave opportunities on the table that more agile rivals exploit.

AI addresses these pressures directly. By automating routine analysis, enhancing human judgment with predictive insights, and enabling real-time decision-making, fashion enterprises can move faster, reduce waste, and capture demand more accurately. The result: improved profitability, reduced markdowns, faster time-to-market, and stronger customer alignment. Organizations that treat AI as a strategic capability see it translate into competitive advantage and shareholder value.

Merchandising: Data-Driven Assortment and Pricing at Scale

Merchandising is where AI delivers immediate, measurable ROI. Fashion enterprises typically manage thousands of SKUs across hundreds of locations, each with unique demand patterns, seasonal variations, and customer preferences. Identifying which products should be displayed prominently, how much inventory each location truly needs, and what price point maximizes profit on each item historically required manual analysis and guesswork by experienced merchants. This approach scaled poorly and left money on the table.

AI systems analyze historical sales data, customer browsing patterns, traffic trends, and external signals like weather and social sentiment to predict demand with precision. These systems recommend assortment mixes by store format and region, flag slow-moving inventory before it becomes a markdown problem, and suggest dynamic pricing that optimizes revenue while maintaining competitiveness. Merchandisers focus their expertise on strategic decisions and creative direction, while AI handles the repetitive pattern recognition and scenario modeling. The outcome is tighter inventory, higher sell-through rates, and improved markdown management across the entire portfolio.

Product Development: Accelerating Concept-to-Market Cycles

Product development in fashion traditionally follows a lengthy process: trend research, design concepting, sample creation, testing, and refinement consume months and millions in investment before a single unit reaches retail. Much of this work involves analyzing trend signals, competitor activity, and consumer preferences—tasks where AI excels. By automating this analysis, fashion enterprises can reduce cycle time, validate ideas faster, and de-risk investment decisions.

AI systems scan global trend signals, social media discussions, runway shows, and search behavior to identify emerging preferences before they reach mainstream awareness. Design teams use these insights to focus creative effort on directions most likely to resonate. AI can also accelerate the testing phase by simulating product performance, predicting fit issues, and identifying which features drive appeal. In some cases, AI assists in concept generation itself, proposing color and silhouette combinations based on learned preferences. The practical impact: enterprises can reduce product development cycle time by 20-30 percent, test more concepts with smaller investment, and launch products when demand peaks rather than six months later.

Retail Operations: From Inventory Visibility to Customer Experience

Once products reach the sales floor, AI continues to optimize. Inventory management systems powered by AI provide real-time visibility across all channels—brick-and-mortar stores, e-commerce sites, fulfillment centers—and recommend transfers to maximize sell-through. These systems account for seasonal patterns, promotional calendars, and location-specific demand, ensuring that the right product is available in the right place at the right time without manual intervention.

Beyond inventory, AI transforms customer-facing operations. Recommendation engines suggest products aligned with each customer’s preferences and purchase history, increasing average order value and customer satisfaction. Chatbots handle routine customer service inquiries efficiently, freeing human associates to provide expert styling advice. Store associate tools powered by AI provide real-time information about inventory, product details, and upsell opportunities, enabling faster transactions and better service. The cumulative effect is a retail operation that runs leaner, serves customers more effectively, and generates more revenue per square foot of retail space.

Implementing AI: Governance, Data Quality, and Organizational Change

Deploying AI at scale requires discipline. Fashion enterprises must establish clear governance frameworks that define which decisions AI can make autonomously, which require human review, and which remain human-directed. These frameworks protect against biased recommendations, ensure compliance with pricing regulations, and maintain brand integrity. Organizations also need robust data governance—AI models are only as good as the data that trains them, and fashion companies must ensure data accuracy, consistency, and privacy across all systems.

Change management is equally critical. AI disrupts established workflows and skill sets. Merchandisers, planners, and designers must understand how to work alongside AI tools and interpret their recommendations effectively. Investment in training, clear communication about how AI will augment rather than replace human expertise, and gradual rollout builds organizational confidence and adoption. The enterprises that execute this transition smoothly capture value faster and more completely than those that treat AI implementation as purely technical.

The Path Forward: Strategic Integration and Competitive Necessity

The fashion industry is undergoing a fundamental shift in how leading enterprises operate. AI has moved from experimental to essential. Organizations that successfully integrate AI across merchandising, product development, and retail operations gain measurable advantages in speed, accuracy, and profitability. Those that remain dependent on manual processes and legacy systems fall behind in competitive intensity.

The competitive opportunity is time-limited. As AI capabilities mature and implementation playbooks become established, the first-mover advantage for sophisticated deployments will narrow. Fashion enterprises that view AI as a strategic investment now—prioritizing data quality, building internal capability, and reshaping processes around AI insights—will establish structural advantages that persist. For boards and leadership teams, the question is no longer whether to invest in AI, but how quickly to move and where to focus investment for maximum impact.

Read more

Why Most AI Collections Initiatives Fail—And How to Build One That Wins

The Trap Every Collections Leader Falls Into

Collections organizations rush to deploy artificial intelligence expecting immediate, dramatic improvements in recovery rates. They implement algorithms, automate communications, and wait for the magic to happen. Six months later, recovery metrics remain flat, compliance risks have actually increased, and teams are working around new systems instead of with them. The problem isn’t AI itself—it’s the approach. Most organizations treat AI implementation as a technology project rather than an operating model transformation. They layer algorithms onto existing broken processes, then wonder why the results disappoint.

Close-up of a man in a blue shirt holding a credit card, symbolizing finance and security. (Photo by Aukid phumsirichat on Pexels)

The gap between AI promise and operational reality widens when collections teams lack a clear map of where intelligence actually creates value. Borrowers don’t care about your machine learning model; they care about fair treatment, clear communication, and workable payment solutions. Yet that human element gets obscured when organizations focus narrowly on automation or cost reduction. The organizations winning today have reframed the question entirely: instead of asking “What can AI do?” they ask “What does our operating model need to win?”

Why Collections Is Uniquely Positioned for AI

Collections operations generate enormous volumes of structured data—payment histories, credit profiles, borrower demographics, interaction logs, and economic indicators. This structured foundation is precisely what machine learning needs to deliver reliable, repeatable insights. Unlike industries fighting through unstructured text or fragmented data sources, collections teams have already built the infrastructure for AI to work effectively. The data infrastructure is less the barrier; execution discipline is.

The work itself also maps naturally to AI’s strengths. Deciding which borrowers to contact, determining optimal contact timing, selecting communication channels, prioritizing which cases warrant human intervention—these are all high-volume, pattern-driven decisions with thousands of daily instances. Each decision carries measurable consequences: successful outreach, avoided defaults, reduced operational cost, or regulatory compliance. This repeatability and measurability mean AI can learn constantly and improve incrementally, turning collections into a continuously optimizing operation rather than a static function.

Crucially, collections already operates under regulatory oversight that forces discipline. Compliance requirements prevent the kind of unchecked experimentation that derails AI initiatives in other industries. Organizations that treat compliance constraints as built-in guardrails rather than obstacles find they develop more robust systems faster. The regulatory environment actually creates accountability that makes AI implementations more disciplined and defensible.

Mapping Value: Where AI Moves the Needle

Successful AI in collections focuses on decisions that directly influence recovery outcomes, operational efficiency, or risk management. The first category centers on borrower engagement—which borrowers to contact, when to reach them, what communication style generates best response, and whether to offer payment arrangements or escalate to more intensive intervention. AI excels at surfacing patterns humans can’t see across millions of historical interactions, then applying those patterns to predict which approaches work for which borrowers in real time.

The second value stream involves resource allocation. Collections teams have finite capacity. Machine learning models can identify which cases a human representative should personally handle versus which can be managed through automated outreach, self-service payment channels, or standard workflows. This isn’t about eliminating human judgment—it’s about concentrating human expertise on cases where human judgment delivers the highest return. A collections representative working exclusively on complex, high-value accounts recovers more than the same person splitting time across routine and complex cases.

The third stream is decisioning and risk management. Early warning systems flag borrowers who may need intervention before they miss payments. Fraud detection catches suspicious patterns. Compliance monitoring ensures every action passes regulatory scrutiny. Predictive models estimate likelihood of recovery so decisions can weight effort against probability of success. These protective and predictive functions run continuously, adjusting to new data as it arrives.

Building the Operating Model That Works

Winning collections organizations start by auditing their current operating model: How are decisions made today? What information flows exist? Where do humans apply judgment versus where do rules apply? Where do delays occur? Where do errors happen? This foundation-level understanding reveals where AI actually creates value versus where it simply automates bad existing processes.

Next comes workflow redesign. AI doesn’t simply replace existing workflows—it fundamentally restructures them. If borrowers currently receive identical outreach, AI enables borrower-specific campaigns. If human representatives manually review every escalation candidate, AI surfaces the highest-value cases for review. If contact timing follows rigid schedules, AI identifies optimal timing for each borrower. The workflow changes are real and significant, and they require change management discipline or they fail.

Data governance becomes non-negotiable at this stage. Models perform only as well as the data training them. Collections data quality varies widely—missing values, inconsistent coding, incomplete histories all degrade model performance. Organizations serious about AI implement data governance practices that standardize how information flows, validate accuracy, and create audit trails. This investment pays dividends across decades of model refinement.

Implementation Priorities: Sequence Matters

Organizations should sequence AI initiatives from highest impact and lowest complexity to higher complexity applications. Start with decisions affecting largest volumes—if tens of thousands of contact decisions happen daily, optimizing that decision generates enormous compounding value. Early wins build confidence and organizational capability. Quick successes in high-volume, well-defined problems create momentum before tackling complex cases requiring deep contextual judgment.

Compliance integration should be front-loaded, not retrofitted. Every decision AI informs must be defensible to regulators. This means audit trails documenting not just what decision was made but why—what data inputs, what model version, what confidence thresholds triggered actions. Organizations that bake compliance into system design from day one avoid costly retrofits and reduce regulatory friction significantly.

Human expertise must remain central to system design. Representatives working collections daily see patterns, edge cases, and borrower needs that historical data alone misses. The most effective implementations treat machine learning as augmenting human judgment rather than replacing it. Representatives armed with AI-generated insights and recommendations, but retaining final decision authority, deliver better outcomes than fully automated systems or representatives working without decision support.

Measuring Success: Beyond Recovery Rates

Collections organizations typically measure AI success narrowly—recovery rate improvement, cost reduction, or volume throughput. These metrics matter, but they’re incomplete. Sustainable implementations also improve collections quality: fewer customer complaints, stronger borrower relationships, reduced regulatory risk, and better employee engagement. Representatives who use AI tools designed to serve their judgment—not replace it—report higher job satisfaction and lower turnover.

The most mature organizations establish balanced measurement frameworks tracking recovery economics, operational efficiency, customer experience, regulatory compliance, and team health simultaneously. This balanced approach reveals trade-offs quickly. If automation is cutting costs but damaging borrower relationships, the model needs adjustment. If recovery rates rise but compliance flags increase, the system needs recalibration. Comprehensive measurement transforms AI from a speculative technology project into a managed operating capability.

The Path Forward: From Technology Project to Competitive Advantage

Collections is one of the few financial functions where AI’s impact is both measurable and immediate. The structured data, high-volume decisions, regulatory clarity, and outcome transparency create ideal conditions for machine learning to deliver value. But that value only materializes when organizations treat AI implementation as an operating model transformation, not a technology installation. Success requires clear mapping of where AI creates value, disciplined change management, strong data governance, and balanced measurement. Organizations that master these fundamentals don’t just improve their collections performance—they build durable competitive advantage in an increasingly technology-driven financial services landscape.

Read more

Strategic Deployment of AI‑Powered Detection Systems in Modern Enterprises

Understanding AI Detectors: Core Concepts and Operating Principles

AI detectors are software systems that apply machine learning to identify patterns indicative of specific conditions, such as fraud, intrusion, or synthetic media. Unlike rule‑based engines that rely on static thresholds, these detectors learn from historical data and continuously refine their decision boundaries. This adaptability allows them to recognize both known signatures and emerging anomalies without manual reprogramming.

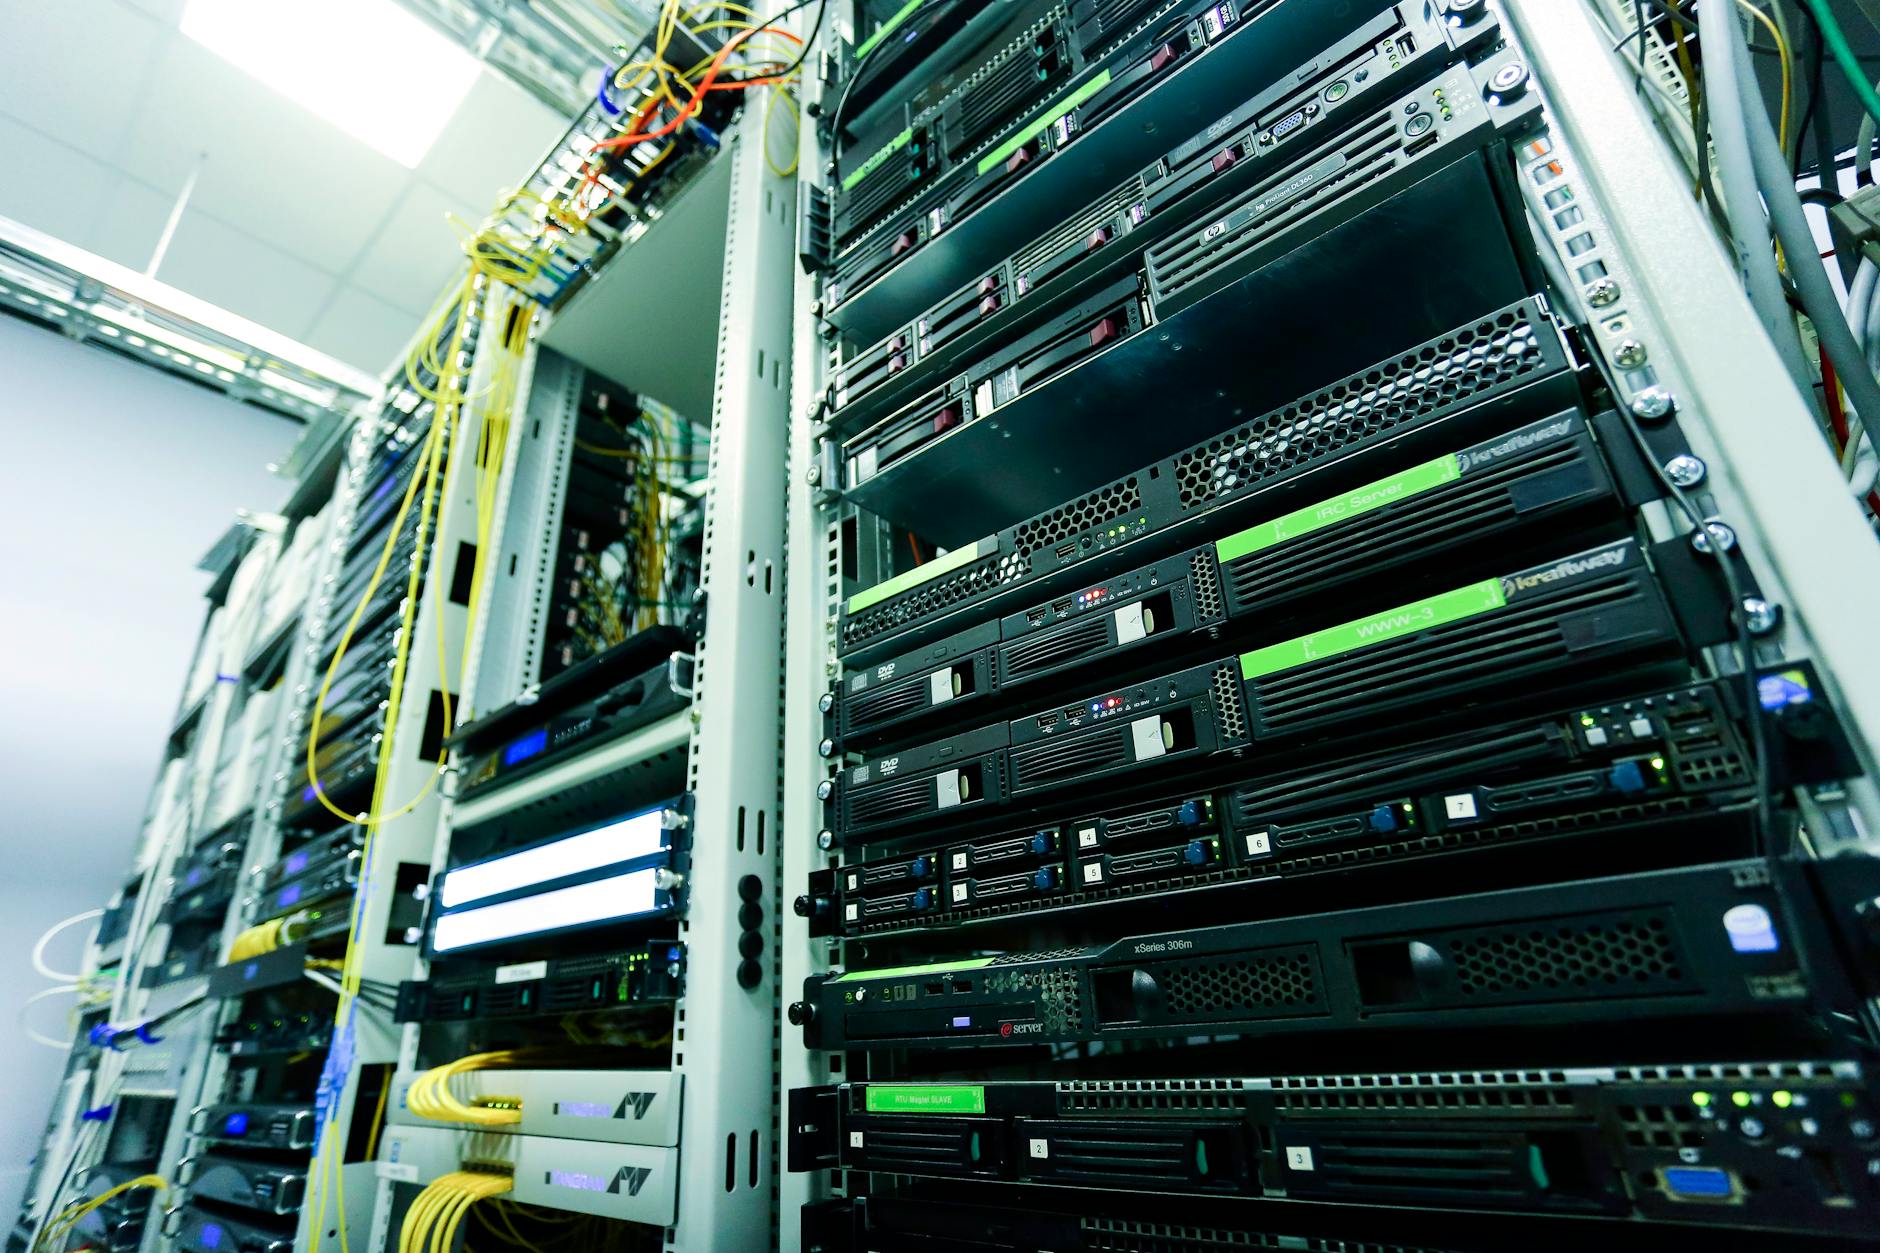
High-tech server rack in a secure data center with network cables and hardware components. (Photo by Sergei Starostin on Pexels)

The typical workflow begins with data ingestion, where raw logs, sensor streams, or content feeds are normalized into a feature vector. Feature engineering extracts statistical, temporal, or semantic attributes that have proven discriminative power in prior incidents. These vectors are then fed to a model trained on labeled examples of normal and anomalous behavior, especially in the context of topic.

Model training may employ supervised techniques when sufficient labeled data exist, or unsupervised methods such as autoencoders and clustering when labels are scarce. In either case, the system updates its parameters periodically—often nightly or in near‑real time—to reflect shifts in the underlying data distribution. This closed‑loop learning is the cornerstone of an AI detector’s ability to stay effective amid evolving threats.

Key Technical Components that Enable Real‑Time Adaptation

Feature extraction pipelines convert disparate data sources into a uniform representation suitable for model consumption. For network traffic, this might include packet size distributions, protocol frequencies, and flow duration statistics. For multimedia, it could involve color histograms, motion vectors, or transformer‑based embeddings. The quality of these features directly influences detection accuracy, with a growing focus on topic solutions.

Model Inference and Scoring

Once features are prepared, the detector runs inference to produce an anomaly score or class probability. Modern deployments leverage GPU‑accelerated inference servers or specialized inference chips to achieve sub‑second latency even at high throughput. Thresholds are dynamically adjusted based on operational risk tolerance, allowing the system to balance sensitivity against alert fatigue.

Feedback and Model Retraining

Detected events are fed back into a labeling queue where analysts verify true positives and false positives. Verified labels augment the training set, triggering a retraining cycle that incorporates the latest observations. Automated drift detection monitors feature distribution changes and can initiate unscheduled retraining when performance degrades beyond a predefined threshold.

Security‑Focused Use Cases: Threat Intelligence and Anomaly Hunting

In network security, AI detectors analyze flow data to spot low‑and‑slow exfiltration attempts that evade signature‑based IDS. By modeling normal traffic baselines, they flag subtle deviations such as unusual port hopping or atypical data volumes. This capability reduces dwell time for attackers who rely on stealth.

Insider threat programs benefit from user‑behavior analytics where each employee’s login frequency, file access patterns, and command‑line usage are continuously scored. Anomalous spikes—such as a finance officer accessing engineering source code at odd hours—trigger investigations before data loss occurs.

Malware classification leverages static and dynamic features extracted from executables, including opcode sequences and API call graphs. Trained models can differentiate between benign utilities and novel ransomware variants, providing a first line of defense that updates as new malware families appear.

Fraud Prevention in Financial Transactions

Payment fraud detection systems ingest transaction streams, evaluating attributes like merchant category, purchase velocity, device fingerprint, and geolocation. By learning from millions of legitimate and fraudulent examples, the detector assigns a risk score that informs real‑time authorization decisions. This approach catches sophisticated schemes such as credential stuffing and synthetic identity fraud.

Anti‑money laundering (AML) applications focus on detecting structuring, layering, and integration patterns across accounts and transaction networks. Graph‑based models examine the topology of fund movements, highlighting circular flows or rapid layering that deviate from typical business behavior. Alerts generated by these models support compliance teams in filing suspicious activity reports.

Identity verification during onboarding uses document authenticity checks combined with behavioral biometrics. AI detectors compare submitted IDs against known templates, scrutinizing micro‑print consistency and hologram patterns, while simultaneously analyzing typing rhythm or mouse movements to detect impersonation attempts.

Content Integrity: Detecting Synthetic Media and Plagiarism

The proliferation of deepfake videos has driven demand for detectors that analyze facial landmarks, eye‑blink frequency, and lighting consistency. Temporal convolutional networks can identify subtle mismatches between audio visemes and lip movements, flagging manipulated content before it spreads on social platforms.

For textual plagiarism, detectors employ transformer embeddings to capture semantic similarity beyond surface‑level n‑gram overlap. By comparing a submitted document against a corpus of academic papers, the system highlights paraphrased passages that retain original meaning but alter wording, supporting academic integrity processes.

Image forensics tools examine noise patterns, compression artifacts, and sensor‑specific anomalies to determine whether a photograph has been spliced or generated by a generative adversarial network. These techniques are valuable in journalism, legal evidence verification, and brand protection pipelines.

Operational Efficiency: Process Anomaly Detection in Manufacturing and Healthcare

In manufacturing, sensor data from CNC machines, robotic arms, and conveyor belts are streamed to AI detectors that monitor vibration spectra, temperature gradients, and power consumption. Early detection of bearing wear or tool misalignment enables predictive maintenance, reducing unplanned downtime and extending equipment life.

Healthcare providers apply similar principles to patient monitoring, where ECG, SpO₂, and respiratory rate streams are analyzed for early signs of sepsis or cardiac arrhythmia. By establishing personalized baselines, the detector alerts clinicians to subtle deteriorations that might be missed during routine checks.

Supply chain analytics use anomaly detection to identify irregularities in shipment timestamps, inventory levels, or supplier performance metrics. Sudden deviations can indicate logistical bottlenecks, fraudulent invoicing, or geopolitical disruptions, allowing planners to reroute resources proactively.

Implementation Roadmap: From Pilot to Enterprise Scale

The first step is a problem‑definition workshop that clarifies the detection objective, success metrics, and data availability. Stakeholders from security, operations, and compliance agree on key performance indicators such as detection rate, false alarm ratio, and mean time to respond. This alignment prevents scope creep and ensures the pilot addresses a tangible business pain point.

Data readiness follows, involving inventory of relevant logs, establishment of secure data pipelines, and application of privacy‑preserving transformations where personally identifiable information is present. Feature stores are populated, and baseline models are trained on historical windows to establish initial performance.

Model selection balances interpretability, latency, and resource consumption. For high‑frequency trading fraud detection, a lightweight gradient‑boosted tree may suffice, whereas video deepfake detection might necessitate a heavier convolutional network. Containerized deployment facilitates seamless movement from a test environment to a production Kubernetes cluster.

Governance frameworks are instituted to oversee model versioning, audit trails, and periodic performance reviews. Clear escalation paths ensure that analyst feedback is incorporated, and that model drift triggers retraining without manual intervention. Documentation of data lineage and model cards supports regulatory compliance and internal audits.

Trade‑offs, Risks, and Mitigation Strategies

One inherent trade‑off is between detection sensitivity and false positive volume. Lowering the decision threshold catches more true anomalies but can overwhelm security teams with noise, leading to alert fatigue. Mitigation involves tiered alerting, where low‑confidence scores trigger automated enrichment while high‑confidence scores generate immediate tickets.

Bias in training data can cause detectors to over‑flag certain demographics or geographic regions, raising fairness and legal concerns. Regular disparity audits, re‑sampling techniques, and the inclusion of diverse label sets help reduce skewed outcomes. Explainability tools such as SHAP values or attention maps provide insight into why a particular instance was scored anomalously.

Computational cost poses a challenge for real‑time applications at scale. Edge inference devices can offload simple scoring tasks, reserving heavyweight models for batch analysis of aggregated events. Capacity planning, autoscaling policies, and efficient feature caching ensure that latency targets are met without excessive infrastructure spend.

Privacy regulations impose constraints on how personal data may be processed for detection purposes. Techniques such as federated learning, differential privacy, and homomorphic encryption enable model improvement while keeping raw data under the custodian’s control. Legal review before deployment confirms that the chosen approach aligns with jurisdictional requirements.

Conclusion: Aligning Detection Capability with Business Objectives

AI detectors transform raw data into actionable intelligence by learning patterns that static rules cannot capture. Their strength lies in continuous adaptation, which is essential when threats, fraud tactics, or operational conditions evolve rapidly. Organizations that invest in robust data pipelines, thoughtful model governance, and clear success metrics can reap measurable reductions in loss, downtime, and reputational risk.

Successful deployment requires a disciplined approach that balances technical sophistication with operational practicality. Pilot projects should validate assumptions about data quality, detection efficacy, and workflow integration before scaling to enterprise-wide rollout. Continuous monitoring, feedback loops, and periodic retraining keep the system effective over its lifecycle.

Ultimately, the value of an AI detector is not measured solely by its technical accuracy but by its contribution to safer transactions, more reliable services, and faster decision‑making. By aligning detection capabilities with defined business goals, enterprises turn a sophisticated analytical tool into a strategic advantage.

References:

  1. https://www.leewayhertz.com/ai-detectors/

AI Detection Systems: Strategic Applications for Modern Enterprises

Foundations of AI Detection Technologies

AI detection systems combine statistical learning, pattern recognition, and adaptive inference to identify deviations from expected behavior. Unlike rule‑based engines that rely on static thresholds, these systems continuously update their internal models as new data arrives. This dynamic adjustment enables them to recognize both known signatures and novel anomalies without manual reprogramming.

A woman plays chess with a robotic arm, illustrating technology and strategy in a modern context. (Photo by Pavel Danilyuk on Pexels)

The core advantage lies in the ability to process heterogeneous data streams—such as network packets, transaction logs, image frames, or text corpora—within a unified analytical framework. By extracting features automatically, the detector reduces the need for manual feature engineering and accelerates deployment across disparate business units.

Implementation typically begins with a data ingestion layer that normalizes inputs, followed by a feature extraction module that employs techniques like embedding vectors, spectral analysis, or temporal windows. The processed features are then fed into a model tier where supervised, unsupervised, or hybrid algorithms generate detection scores.

Core Architectural Components of Detection Engines

A robust detection engine comprises four interconnected layers: acquisition, preprocessing, model inference, and response orchestration. The acquisition layer captures raw telemetry from sensors, APIs, or log aggregators and ensures temporal alignment across sources. Proper buffering and fault‑tolerant transport prevent data loss during peak loads, especially in the context of AI content detection tools.

In the preprocessing stage, data undergoes cleansing, normalization, and transformation. Techniques such as outlier clipping, missing‑value imputation, and dimensionality reduction prepare the data for consistent model consumption. Feature stores often serve as reusable repositories, enabling multiple detectors to share engineered attributes.

The model inference layer hosts the machine learning models that produce anomaly scores or classification probabilities. Depending on latency requirements, inference may occur on‑premise GPUs, edge ASICs, or managed cloud services. Finally, the response layer translates scores into actionable alerts, automated remediation workflows, or forensic data packages for further investigation.

Real‑Time Threat Identification in Cybersecurity

Modern networks generate telemetry at rates that exceed the capacity of manual analysis. AI detectors address this by continuously scoring traffic patterns, login sequences, and file access events for signs of compromise. Because they learn baseline behavior per asset, they can flag subtle deviations that signature‑based tools miss.

Signature‑Based versus Anomaly‑Based Approaches

Signature‑based detectors excel at catching known malware variants or exploit kits where deterministic patterns exist. Anomaly‑based detectors, powered by unsupervised clustering or autoencoders, uncover zero‑day activities by measuring statistical distance from learned norms. A hybrid deployment leverages signatures for rapid blocking and anomalies for deeper hunting.

Operational considerations include model drift detection, where shifts in network topology or application usage degrade detection fidelity. Periodic retraining windows, coupled with online learning mechanisms, maintain accuracy without requiring full pipeline redeployment. Alert fatigue is mitigated by tiered scoring, where low‑confidence events trigger enrichment rather than immediate blocking.

Fraud Prevention Across Financial Transactions

Financial institutions confront sophisticated fraud schemes that evolve faster than static rule sets can adapt. AI detectors analyze transactional attributes—such as amount, merchant category, geolocation, and device fingerprint—in real time to compute risk scores. By correlating these signals across accounts, the system identifies coordinated attack patterns like credential stuffing or synthetic identity creation.

The detection workflow often starts with a lightweight model that filters obvious legitimate transactions, reserving deeper analysis for borderline cases. This cascade design reduces computational load while preserving high recall for fraudulent activity. When a score exceeds a configurable threshold, the system can invoke step‑up authentication, transaction holds, or fraud analyst queues.

Effective deployment demands close alignment with regulatory frameworks governing data privacy and consumer protection. Model explainability features, such as SHAP values or counterfactual explanations, support audit trails and facilitate dispute resolution. Continuous monitoring of false positive rates ensures that legitimate commerce is not unduly impeded.

Multimedia Authenticity and Deep‑Fake Mitigation

The proliferation of synthetic media challenges trust in visual and auditory content. AI detectors designed for media authenticity employ convolutional and recurrent networks to inspect subtle inconsistencies—such as irregular blinking patterns, unnatural audio‑visual synchronization, or compression artifacts indicative of generative models.

In practice, a detector processes each frame or audio segment, extracting spatio‑temporal features that are fed into a binary classifier. The output is a confidence score reflecting the likelihood of manipulation. For video, temporal coherence models can detect abrupt changes in lighting or pose that are difficult for deep‑fake generators to replicate convincingly.

Organizations integrate these detectors into content moderation pipelines, social media monitoring tools, and digital rights management systems. Because manipulation techniques evolve rapidly, continuous model updating with adversarial training helps the detector stay ahead of emerging generative methods. Latency constraints are addressed by deploying lightweight model variants at the edge, reserving full‑scale analysis for high‑value assets.

Operational Anomaly Detection in Manufacturing and Supply Chains

Production equipment emits streams of sensor data—vibration, temperature, pressure, and power consumption—that reflect underlying health states. AI detectors learn the normal operating envelopes of machines and can forecast impending failures by recognizing early‑warning patterns. This predictive capability shifts maintenance from reactive schedules to condition‑based interventions.

In supply chain contexts, detectors monitor logistics metrics such as transit times, inventory turnover, and carrier performance. Anomalies in these signals may indicate disruptions like port congestion, customs delays, or fraudulent documentation. By surfacing deviations promptly, planners can reroute shipments or adjust safety stock levels before service levels degrade.

Successful implementation hinges on data quality and sensor fidelity. Calibration routines, redundant sensing, and edge‑based preprocessing reduce noise that could otherwise trigger false alarms. Moreover, integrating detector outputs with computerized maintenance management systems (CMMS) or enterprise resource planning (ERP) platforms enables automated work order generation and closed‑loop improvement.

Text‑Based Misuse Detection: Plagiarism, Spam, and Policy Enforcement

Large volumes of textual content—ranging from internal communications to public‑facing posts—require continuous scrutiny for policy violations, intellectual property infringement, or abusive language, and spam. AI detectors leverage transformer‑based language models to capture semantic meaning beyond simple keyword matching, enabling them to detect paraphrased plagiarism or contextually harmful speech.

The detection pipeline typically tokenizes input, passes it through a pretrained encoder, and applies a classification head that outputs labels such as “original,” “potentially plagiarized,” or “non‑compliant.” Thresholds are tuned per use case; for academic integrity checks, a high precision setting may be preferred to avoid false accusations, whereas moderation platforms might prioritize recall to catch elusive harmful content.

Deployment challenges include handling multilingual corpora and adapting to evolving slang or code‑switched language. Continuous fine‑tuning on domain‑specific corpora, coupled with active learning where uncertain samples are sent for human review, sustains detector effectiveness over time. Explainability tools that highlight influential tokens assist auditors in understanding why a piece of content was flagged.

Workforce Analytics and Productivity Monitoring

Enterprises increasingly rely on digital signals—application usage logs, keystroke dynamics, meeting metadata—to assess workforce behavior and identify productivity trends. AI detectors model normal work patterns for individuals or teams and flag deviations that may signal burnout, disengagement, or insider risk. Because the signals are behavioral rather than transactional, privacy safeguards are paramount.

A typical implementation aggregates anonymized activity streams into feature vectors representing focus time, context‑switch frequency, and collaboration intensity. Unsupervised clustering identifies natural productivity archetypes, while supervised models can predict outcomes such as project delivery risk based on historical correlations. Alerts are directed to managers or HR partners with contextual summaries rather than raw data, preserving employee confidentiality.

Ethical considerations dictate transparent policies, opt‑in mechanisms, and strict access controls. Detectors should be audited regularly for bias that could disproportionately affect certain roles or demographics. When used responsibly, these systems support data‑driven coaching, workload balancing, and early intervention programs that enhance both organizational performance and employee well‑being.

Conclusion: Building a Scalable AI Detection Framework

AI detection systems deliver a versatile foundation for addressing security, fraud, integrity, and operational challenges across the enterprise. Their strength lies in the ability to learn from data, adapt to emerging patterns, and integrate with existing monitoring and response infrastructures. Successful adoption requires a clear architecture that separates ingestion, preprocessing, inference, and action, coupled with rigorous governance around model lifecycle, explainability, and privacy.

Organizations should begin with well‑defined use cases, establish baseline performance metrics, and iterate through pilot phases before scaling to enterprise‑wide deployment. Continuous learning, feedback loops from analysts, and periodic model refreshes ensure detectors remain effective as threats and business conditions evolve. By treating detection as a living capability rather than a static tool, enterprises can maintain resilience in an increasingly complex digital landscape.

References:

  1. https://www.leewayhertz.com/ai-detectors/

Strategic Guide to Building Enterprise AI Chatbot Solutions

Understanding Business Drivers for Conversational AI

Enterprises adopt chatbots to reduce response latency, free human agents from repetitive inquiries, and capture interaction data for continuous improvement. The primary motivation is often to scale support channels without proportional headcount increase while maintaining service quality. Decision makers evaluate whether a conversational interface can address peak‑load scenarios, multilingual demands, or after‑hours coverage gaps.

Hand holding a smartphone with AI chatbot app, emphasizing artificial intelligence and technology. (Photo by Sanket  Mishra on Pexels)

Another driver is the desire to unify disparate knowledge bases—product documentation, internal wikis, ticketing systems—into a single conversational entry point. By doing so, organizations aim to lower the average time to resolution and improve employee self‑service rates. Stakeholders also consider the potential for upselling or cross‑selling when chatbots guide users toward relevant offers during support interactions, especially in the context of AI chatbot development company.

Finally, regulatory and compliance considerations shape the scope. Industries such as finance or healthcare require audit trails, data residency controls, and explicit consent mechanisms. Early alignment with legal and security teams ensures that the chatbot architecture satisfies these constraints before development begins.

Conducting a Needs Assessment and Defining Scope

The assessment begins with a workshop that maps current touchpoints—web, mobile app, internal portal, phone IVR—to pain points such as high call abandonment, frequent password reset requests, or delayed order status updates. Participants quantify volume, frequency, and business impact of each issue using existing analytics or help‑desk reports. This data‑driven baseline informs prioritization, especially in the context of AI chatbot development company solutions.

Next, the team defines functional scope by answering three questions: Which user intents are high‑volume and low‑complexity? Which intents require access to transactional systems (e.g., account balance, inventory)? Which intents demand empathy or judgment beyond automation? The outcome is a tiered intent matrix that separates candidates for full automation, assisted handoff, or human‑only handling.

Deliverables from this phase include a scoped use‑case catalog, success metrics (e.g., target containment rate, average handling time reduction), and a risk register covering data privacy, integration complexity, and change‑management resistance. The catalog becomes the contract between business sponsors and the technical team, preventing scope creep later in the project.

Designing Conversational Flows and User Experience

Design starts with intent clustering and sample utterance generation. Linguists or conversation designers rewrite raw user phrases into canonical forms, ensuring coverage of synonyms, abbreviations, and typos. Each intent is assigned a confidence threshold that determines when the bot can respond autonomously versus when it should seek clarification or escalate.

Dialogue states are then modeled using a flow‑chart or state‑machine representation. Designers map out happy paths, fallback branches, and context‑switching rules (e.g., moving from order status to return initiation). Visual prototyping tools allow stakeholders to walk through scenarios before any code is written, catching logical gaps early.

Balancing Scripted and Generative Responses

For predictable, transactional intents, rule‑based or slot‑filling approaches provide deterministic outcomes and simplify testing. For open‑ended queries—such as product recommendation or troubleshooting advice—generative models powered by large language models offer flexibility but require careful grounding to avoid hallucinations. A hybrid strategy routes low‑risk generative outputs through a validation layer that checks factual consistency against approved knowledge sources before delivery.

User experience considerations extend to tone, branding, and accessibility. The bot’s language style is aligned with corporate voice guidelines, while UI components adhere to WCAG 2.1 AA standards for keyboard navigation and screen‑reader compatibility. Multilingual support is planned by separating language detection from intent recognition, enabling the same dialogue model to serve multiple locales with localized response templates.

Selecting the Appropriate Technology Stack

Architecture decisions hinge on three layers: natural language understanding (NLU), dialogue management, and fulfillment. For NLU, teams choose between cloud‑provided APIs that offer pretrained models with continuous updates, or open‑source frameworks that allow on‑premises training for data‑sovereignty requirements. The trade‑off involves operational control versus upfront model‑training effort.

Dialogue management can be handled by state‑machine engines, rule‑based scripts, or reinforcement‑learning‑based policies. State‑machine engines provide transparency and ease of debugging, making them suitable for regulated environments. Reinforcement‑learning policies adapt over time but demand extensive simulation and monitoring to prevent policy drift.

Fulfillment connects the dialogue layer to backend services via APIs, message queues, or robotic process automation. Synchronous REST calls work well for low‑latency lookups (e.g., checking order status), while asynchronous event‑driven patterns suit longer‑running processes (e.g., initiating a refund). Security controls such as OAuth 2.0, mutual TLS, and token scoping are applied at this layer to protect sensitive data.

Planning and Executing System Integration

Integration begins with an interface inventory that lists all systems the chatbot must read from or write to—CRM, ERP, knowledge base, ticketing, and telephony platforms. For each system, the team documents authentication mechanisms, data formats, rate limits, and sandbox availability. This inventory drives the creation of integration adapters that normalize disparate protocols into a uniform internal contract.

Data consistency is addressed through a canonical data model that maps fields from source systems to chatbot‑specific objects. For example, a customer identifier may exist as “AccountNumber” in the CRM and “ClientID” in the billing system; the adapter translates both to a universal “customerId”. Change‑data‑capture streams or periodic sync jobs keep the chatbot’s cached reference data up to date without overloading source systems.

Testing integration involves contract tests that validate request/response schemas, performance tests that simulate peak concurrent users, and failure‑injection tests that verify graceful degradation when a downstream service is unavailable. Deploying adapters behind an API gateway enables centralized throttling, logging, and version rollback.

Managing Deployment, Training, and Change Adoption

A phased rollout reduces risk: the chatbot is first exposed to a small internal pilot group (e.g., IT help desk) to validate core flows and collect feedback. Metrics such as fallback rate and user satisfaction are monitored daily. Based on pilot outcomes, the team refines intent thresholds, updates training utterances, and adjusts escalation rules before expanding to a broader audience.

End‑user training consists of concise in‑app tutorials, short video demos, and FAQ articles, and live webinars that highlight the bot’s capabilities and limitations. Clear communication about when to expect a human hand‑off prevents frustration. For employee‑facing bots, supervisors receive dashboards showing conversation volumes, escalation trends, and knowledge‑gap alerts to guide coaching.

Change‑management plans address cultural resistance by positioning the chatbot as an augmentation tool rather than a replacement. Success stories—such as a 30 % reduction in password‑reset tickets—are shared via internal newsletters. Feedback loops, including a “thumbs‑up/down” button after each interaction, provide continuous sentiment data that informs iterative improvements.

Establishing Ongoing Monitoring, Maintenance, and Improvement

Operational observability rests on three pillars: conversation analytics, system health, and model performance. Analytics dashboards track containment rate, average turn‑time, sentiment scores, and topic clustering to surface emerging intents. System health monitors API latency, error rates, and resource utilization to detect infrastructure bottlenecks.

Model performance is evaluated through weekly sampling of logged utterances. Human reviewers label a subset for correctness, enabling calculation of precision, recall, and F‑score per intent. When drift is detected—indicated by a sustained drop in confidence scores—the team retrains the NLU model using the latest labeled data, incorporating new product names, policy changes, or seasonal phrasing.

Maintenance cycles include scheduled updates to integration adapters, security patches for underlying platforms, and version upgrades of third‑party services. A rollback procedure is documented and tested quarterly to ensure rapid recovery from faulty releases. All changes pass through a change‑advisory board that reviews impact assessments, test results, and stakeholder sign‑off before promotion to production.

Measuring Impact and Calculating Return on Investment

Financial justification starts with baseline cost calculations: average handling time per query, fully loaded agent cost, and volume of queries handled by human agents before chatbot deployment. Post‑deployment, the same metrics are recomputed for the subset of queries now managed by the bot. The difference yields direct labor savings.

Indirect benefits are captured through improved customer satisfaction scores (e.g., Net Promoter Score uplift), reduced abandon rates in sales funnels, and increased compliance adherence due to consistent disclosure delivery. These benefits are monetized using established conversion rates or penalty avoidance estimates.

Payback period is computed by dividing total implementation cost—including consulting, development, licensing, and training—by the monthly net benefit (direct plus indirect). Sensitivity analysis varies key assumptions such as containment rate growth and agent wage inflation to present a range of outcomes. Decision makers use this analysis to justify continued investment or to scope additional use‑cases for expansion.

Conclusion: Building a Sustainable AI Chatbot Practice

A successful enterprise chatbot initiative treats the technology as a capability that evolves alongside business needs, rather than a one‑off project. By institutionalizing the needs‑assessment, design, integration, and monitoring cycles described above, organizations create a repeatable framework for adding new intents, languages, or channels with predictable effort and risk.

Continuous improvement hinges on closing the loop between user feedback, model retraining, and process refinement. When governance, security, and user‑excellence are embedded from the outset, the chatbot becomes a reliable conduit for information, transaction execution, and experience enhancement—delivering measurable returns while freeing human talent to focus on higher‑value activities.

Explore more at LeewayHertz

Strategic Implementation of Enterprise AI Agents for Measurable Business Impact

Understanding the Operational Challenges That AI Agents Address

Many enterprises face rising pressure to accelerate decision cycles while controlling operational costs. Manual processes in areas such as data gathering, report generation, and routine inquiries consume valuable employee time and introduce variability in outcomes. Leaders seek solutions that can handle repetitive tasks consistently, free up talent for higher‑value work, and provide timely insights without expanding headcount.

Software developer analyzing code on a tablet in a modern office workspace. (Photo by Jakub Zerdzicki on Pexels)

AI agents offer a programmable layer that can perceive context, reason over information, and act within defined boundaries. Unlike static automation scripts, these agents adapt to changing inputs, learn from feedback, and coordinate across multiple systems. When aligned with clear business objectives, they become a force multiplier for productivity and accuracy, especially in the context of AI agent development company.

Before embarking on an agent initiative, stakeholders must articulate the specific pain points they intend to solve. This clarity drives downstream decisions about agent type, complexity, and integration points, ensuring that technology investment translates directly into measurable improvements.

Conducting a Readiness Assessment and Defining Clear Objectives

The first step in any agent project is a systematic evaluation of current workflows, data availability, and organizational capabilities. Analysts map end‑to‑end processes, identify bottlenecks, and quantify the cost of manual effort. This baseline informs the potential return on investment and highlights where agents can deliver the greatest leverage, with a growing focus on AI agent development company solutions.

Simultaneously, leadership must define success metrics that are specific, measurable, and tied to business outcomes. Examples include reducing average handling time for customer inquiries by a certain percentage, increasing the frequency of timely financial close activities, or improving the quality of risk assessments through automated scenario analysis. Clear metrics guide agent design and provide a basis for ongoing performance tracking.

The assessment also uncovers governance requirements such as data privacy, model explainability, and regulatory compliance. Early identification of these constraints shapes the selection of underlying technologies and informs the design of monitoring controls that will be needed throughout the agent lifecycle.

Choosing the Appropriate Agent Architecture and Underlying Models

Agent architectures vary from simple reflexive bots that follow rule‑based logic to sophisticated reasoning agents that leverage large language models for dynamic planning. The choice hinges on the complexity of tasks, the need for contextual understanding, and the variability of inputs. For highly structured processes such as invoice matching, a deterministic agent may suffice, whereas nuanced activities like market sentiment analysis benefit from generative capabilities.

Selecting the right foundation model involves trade‑offs between model size, inference latency, and cost. Smaller models offer faster response times and lower operational expense but may struggle with ambiguous language. Larger models provide richer comprehension at the expense of higher compute requirements. Organizations often start with a mid‑range model to validate concepts before scaling to larger variants if performance demands increase.

Beyond the core model, the agent framework must support essential capabilities such as memory retention, tool usage, and multi‑step planning. Frameworks that expose standardized APIs for calling external services, accessing knowledge bases, and managing state simplify integration and future extensibility. Evaluating framework maturity, community support, and compatibility with existing enterprise infrastructure is critical at this stage.

Designing, Prototyping, and Validating Custom Agents

Once the architectural direction is set, teams move to detailed design. This involves specifying the agent’s perception module (how it ingests data), its reasoning module (how it derives actions), and its action module (how it executes tasks). Design documents outline data schemas, prompt structures, error handling procedures, and fallback mechanisms to ensure robustness.

Prompt engineering becomes a central activity for agents that rely on language models. Practitioners craft prompts that elicit consistent, accurate responses while minimizing hallucinations. Techniques such as few‑shot examples, chain‑of‑thought reasoning, and output constraints are tested iteratively. A dedicated prompt library is maintained to facilitate reuse across similar use cases.

Prototyping follows a rapid‑cycle approach. Developers build a minimal viable agent that can perform a core subset of the intended workflow. This prototype is exercised against real or simulated data, and stakeholders review outputs for correctness and relevance. Feedback loops refine prompts, adjust model parameters, and uncover integration gaps before full‑scale development begins.

Data Preparation and Knowledge Integration

Effective agents depend on high‑quality, well‑structured data. Teams curate relevant datasets, apply cleaning routines, and establish pipelines that keep information current. For agents that need to reference policies, product catalogs, or historical transactions, a knowledge base is indexed and made queryable via semantic search or retrieval‑augmented generation.

Security controls are applied to data access, ensuring that the agent only retrieves information authorized for its role. Encryption at rest and in transit, along with role‑based access controls, protect sensitive content. Monitoring logs capture every data access event, supporting audit trails and anomaly detection.

Integrating Agents into Existing Enterprise Workflows

Integration begins with mapping the agent’s touchpoints to current applications, databases, and user interfaces. APIs are exposed or consumed to enable bi‑directional data flow. Where legacy systems lack modern interfaces, middleware adapters translate between the agent’s protocols and the system’s native formats.

Microservices architecture is frequently employed to encapsulate agent functions, allowing independent scaling and deployment. Containers package the agent runtime, its dependencies, and configuration scripts, promoting consistency across development, testing, and production environments. Orchestration platforms manage load balancing, health checks, and rolling updates.

Latency considerations drive decisions about where agent compute resides. For latency‑sensitive interactions such as real‑time chat support, agents may be deployed close to the user interface layer, possibly at the edge. Background processes like batch data enrichment can run in centralized compute clusters where resources are more abundant.

Change management practices accompany technical integration. End‑user training materials explain how to invoke the agent, interpret its suggestions, and escalate when needed. Support teams receive runbooks that detail troubleshooting steps and contact points for model‑related issues.

Establishing Governance, Monitoring, and Continuous Improvement

Governance frameworks define who is responsible for agent performance, model updates, and compliance oversight. A cross‑functional committee typically includes representatives from data science, IT security, legal, and business operations. This body reviews change requests, approves model retraining schedules, and ensures that agents remain aligned with corporate policies.

Monitoring instrumentation captures key performance indicators such as response latency, success rate of actions, and frequency of fallback to human operators. Anomaly detection algorithms flag deviations that may indicate data drift, model degradation, or emerging security threats. Dashboards provide real‑time visibility to stakeholders and trigger alerts when thresholds are breached.

Continuous improvement relies on a feedback loop where user corrections and outcome data are fed back into model training pipelines. Periodic retraining cycles incorporate new examples, adjust prompt templates, and refresh knowledge bases. Version control tracks model artifacts, enabling rollback if a new release introduces unintended behavior.

Managing Risk and Ensuring Compliance

Risk assessments examine potential harms ranging from erroneous recommendations to unauthorized data exposure. Mitigation strategies include setting confidence thresholds that trigger human review, implementing output sanitization to remove sensitive content, and enforcing strict access scopes for each agent role.

Compliance checks verify that agents adhere to regulations such as GDPR, HIPAA, or industry‑specific standards. Automated scans evaluate whether generated content contains protected personal information, while audit logs confirm that data handling respects consent and retention policies. Regular third‑party reviews add an extra layer of assurance.

Deploying Agents Across Functional Domains

In customer service, agents can triage incoming inquiries, retrieve relevant knowledge articles, and suggest responses that agents or human representatives can edit and send. By handling routine questions, they reduce average handle time and allow staff to focus on complex cases that require empathy or negotiation. Continuous learning from resolved tickets improves the accuracy of suggested replies over time.

Human resources departments benefit from agents that screen resumes against predefined competency models, schedule interviews, and answer employee queries about policies or benefits. During onboarding, agents guide new hires through required documentation, training modules, and access provisioning steps, creating a consistent experience while reducing administrative load.

Finance teams deploy agents for tasks such as expense report validation, invoice matching, and variance analysis. Agents extract data from receipts, compare it against corporate travel policies, and flag exceptions for review. In close processes, they reconcile ledger entries, generate preliminary financial statements, and provide explanations for significant fluctuations, accelerating the overall cycle.

Supply chain operations use agents to monitor inventory levels, predict demand spikes, and trigger replenishment orders. By ingesting data from ERP systems, IoT sensors, and external market feeds, agents can recommend optimal reorder points and suggest alternative suppliers when lead times lengthen. The result is a more responsive network that minimizes stockouts and excess inventory.

Measuring Impact, Scaling the Program, and Sustaining Value

After deployment, organizations compare actual performance against the baseline established during the readiness assessment. Improvements are expressed in terms of time saved, cost avoided, error reduction, or revenue uplift. These quantitative results validate the initial business case and inform decisions about expanding agent coverage to additional processes or departments.

Scaling considerations include standardizing agent development practices, creating reusable components, and establishing a center of excellence that governs model lifecycle management. Template repositories for prompts, data connectors, and testing scripts accelerate new projects while maintaining quality thresholds. Training programs cultivate internal expertise, reducing reliance on external specialists.

Finally, sustaining value requires treating AI agents as living assets rather than one‑time installations. Regular health checks, periodic retraining, and ongoing stakeholder engagement ensure that agents evolve alongside changing business needs. By embedding agents into the fabric of enterprise operations, companies unlock a durable source of efficiency, insight, and competitive advantage.

Read more

How Intelligent Automation Is Redefining Modern Production Lines

Manufacturers worldwide are confronting a paradox: demand for higher quality, faster delivery, and lower cost is rising, while labor shortages and supply‑chain volatility intensify. Traditional process‑control methods, which rely on static rules and manual oversight, no longer provide the agility needed to stay competitive. To bridge this gap, enterprises are turning to data‑driven intelligence that can learn, adapt, and act in real time across every stage of production.

Two young professionals working on laptops in a modern cafe setting. (Photo by Canva Studio on Pexels)

At the heart of this shift lies a new generation of software agents capable of interpreting sensor streams, optimizing workflows, and even predicting equipment failures before they happen. By embedding these capabilities into the factory floor, companies are creating self‑optimizing ecosystems that continuously improve productivity, safety, and profitability. The most compelling evidence of this transformation can be found in the expanding scope of AI applications for manufacturing, which are turning once‑static assembly lines into dynamic, learning systems.

Predictive Maintenance: Turning Downtime into Data‑Driven Opportunity

Equipment failure has historically been treated as an inevitable cost of doing business, often addressed only after a breakdown occurs. Predictive maintenance flips this narrative by leveraging machine‑learning models that analyze vibration signatures, temperature trends, and power consumption to forecast wear patterns. When a model detects an anomaly—say, a subtle increase in bearing temperature—it triggers a maintenance ticket, schedules a technician, and even suggests the optimal replacement part.

Real‑world implementations illustrate the impact. A mid‑size automotive parts supplier reduced unplanned downtime by 38 % within the first year of deploying a cloud‑based predictive platform. The solution integrated legacy PLC data with a neural network trained on historical failure logs, delivering alerts that were both accurate and actionable. As a result, the plant not only avoided costly line stops but also extended the mean time between failures (MTBF) of critical CNC machines by more than 20 %.

Key considerations for rollout include ensuring high‑frequency data capture, establishing clear thresholds for alert escalation, and fostering cross‑functional collaboration between operations, IT, and maintenance teams. Without these foundations, the sheer volume of sensor data can become overwhelming, diluting the value of the insights generated.

Quality Assurance Reinvented Through Vision‑Based AI

Traditional quality checks often involve human inspectors performing spot checks or relying on simple statistical process control (SPC) charts. Vision‑based AI elevates this approach by deploying deep‑learning models that can detect microscopic defects—such as surface scratches, misaligned components, or color deviations—in fractions of a second. The technology operates continuously, scanning every item that passes through the line and flagging out‑of‑spec products for immediate remediation.

Consider the case of a consumer electronics assembler that introduced an AI‑powered inspection system on its final‑test station. The solution achieved a defect detection rate of 99.7 % compared to 92 % for manual inspection, while simultaneously cutting inspection time per unit from 2.3 seconds to 0.4 seconds. The downstream benefits were significant: scrap rates fell by 45 %, warranty claims dropped, and overall customer satisfaction scores rose sharply.

Successful adoption hinges on high‑resolution imaging hardware, well‑annotated training datasets, and a feedback loop that incorporates operator corrections back into the model. Moreover, integrating the AI system with Manufacturing Execution Systems (MES) enables automatic segregation of defective units and real‑time reporting to quality managers.

Supply‑Chain Synchronization via AI‑Enabled Demand Forecasting

Accurate demand forecasting is the linchpin of efficient inventory management, yet it remains one of the most error‑prone activities in manufacturing. AI models that fuse historical sales data, market trends, promotional calendars, and even external signals such as weather forecasts can produce forecasts with markedly lower mean absolute percentage error (MAPE) than conventional statistical methods.

A leading consumer‑goods manufacturer piloted a transformer‑based forecasting engine across its European plants. The model achieved a 15 % reduction in forecast error, enabling the firm to trim safety stock by 12 % and reduce lead times without compromising service levels. The resulting inventory cost savings amounted to millions of dollars annually, while also freeing warehouse space for new product introductions.

Implementation best practices include robust data governance to ensure clean, timely inputs, as well as a phased deployment that starts with high‑impact product families before scaling across the portfolio. Aligning the forecasting output with downstream planning tools—such as advanced planning and scheduling (APS) systems—ensures that the improved visibility translates into actionable production schedules.

Human‑Machine Collaboration: Augmented Decision‑Making on the Shop Floor

While autonomous AI agents can handle routine optimization tasks, the most valuable outcomes arise when they serve as decision‑support partners for skilled operators. Augmented reality (AR) interfaces, powered by AI analytics, can overlay real‑time performance metrics, energy consumption data, and suggested process adjustments directly onto a worker’s line‑of‑sight. This empowers operators to make informed tweaks without leaving their stations.

In a high‑precision metal‑fabrication plant, technicians equipped with AR glasses received AI‑generated recommendations for cutting speed adjustments based on real‑time tool wear assessments. The immediate adoption of these suggestions led to a 7 % increase in material utilization and a 4 % reduction in cycle time. Importantly, the system logged each interaction, creating a knowledge base that further refined the AI models.

Critical to success is designing intuitive user experiences that avoid information overload, establishing clear authority hierarchies for AI recommendations, and providing training that builds trust in the technology. When workers perceive AI as a collaborative ally rather than a replacement, adoption rates soar and overall plant performance improves.

Strategic Roadmap for Integrating Intelligent Automation

Transitioning from isolated AI experiments to enterprise‑wide intelligent automation requires a disciplined roadmap. The first step is to conduct a capability audit, mapping existing data sources, legacy control systems, and staffing structures. This inventory informs the selection of pilot projects—often those with high data availability and clear ROI, such as predictive maintenance or vision‑based inspection.

Subsequent phases should focus on building a scalable architecture that includes edge compute for low‑latency inference, cloud services for model training, and robust APIs for system integration. Governance frameworks must be established to oversee model versioning, data privacy, and compliance with industry standards. Finally, a continuous improvement loop—driven by performance metrics, operator feedback, and periodic model retraining—ensures that the AI ecosystem evolves alongside changing business needs.

Companies that execute this roadmap methodically can expect measurable gains: reduced operational expenditures, higher product quality, and a more agile response to market fluctuations. By embedding intelligent automation at the core of their manufacturing strategy, they position themselves not only to survive the Industry 4.0 wave but to lead it.

Read more

Design a site like this with WordPress.com
Get started